OpenAI
GPT-6.1 Sol
- $2 / $10
- per 1M input / output
- $0.10
- per 1M cached input, 95% off
- 72¢
- per task on Artificial Analysis, 1 point below Astra
The new Codex default. Peter has it 4th on Code Arena, above Fable.
On air at 24:57 →ThursdAIThursday, Oct 1, 20261:57:29Live from CoreWeave Fully Connected
This one was special. We came to you LIVE from the middle of the show floor at Moscone, from CoreWeave's Fully Connected, with robots walking behind us and a Vera Rubin rack a few feet away. Three big models this week, OpenAI's biggest DevDay ever, and the story I've been yelling about for weeks finally went mainstream: OpenAI joined the AI assistant race.
Alex's read, from the show. Muse and Grokbot were last week's story.
Every timestamp on this page jumps the player there. The podcast and the video share one clock.
Hour one · the newsHour two · from the floorBreaking
Three new models in one week
Peter's verdict, which I had to repeat straight to the camera: no. Opus 5.5 is enough. GPT-6.1 Sol is enough. For Navier-Stokes level problems, sure, reach for the big ones. Maybe THIS is what pacing the frontier looks like 🤔
OpenAI
The new Codex default. Peter has it 4th on Code Arena, above Fable.
On air at 24:57 →Anthropic
LDJ: the new best free model for friends and family.
On air at 36:00 →Google DeepMind
Government and trusted cyber defenders first. You probably can't use it yet.
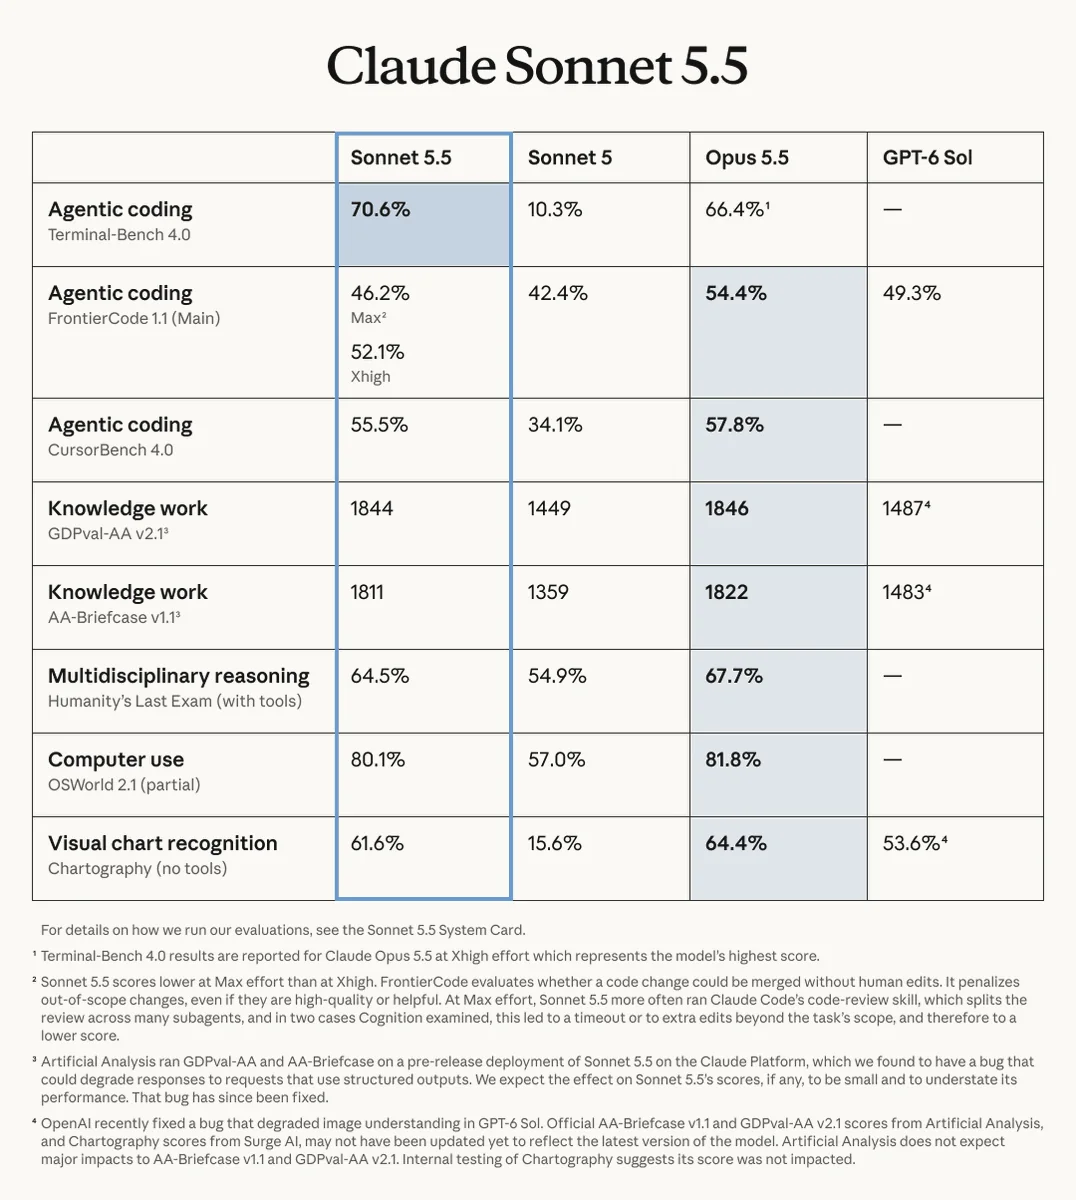
On air at 41:05 →| Benchmark | Sonnet 5.5 | Sonnet 5 | Opus 5.5 | GPT-6 Sol |
|---|---|---|---|---|
| Agentic codingTerminal-Bench 4.0 | 70.6% | 10.3% | 66.4% | — |
| Agentic codingFrontierCode 1.1 (Main) | 52.1% | 42.4% | 54.4% | 49.3% |
| Agentic codingCursorBench 4.0 | 55.5% | 34.1% | 57.8% | — |
| Knowledge workGDPval-AA v2.1 | 1844 | 1449 | 1846 | 1487 |
| Knowledge workAA-Briefcase v1.1 | 1811 | 1359 | 1822 | 1483 |
| Multidisciplinary reasoningHumanity's Last Exam (with tools) | 64.5% | 54.9% | 67.7% | — |
| Computer useOSWorld 2.1 (partial) | 80.1% | 57.0% | 81.8% | — |
| Visual chart recognitionChartography (no tools) | 61.6% | 15.6% | 64.4% | 53.6% |
Vendor-reported. Opus 5.5 on Terminal-Bench 4.0 at xhigh effort; Sonnet 5.5 on FrontierCode at xhigh (46.2% at max). Highlighted cells are the best score in each row.
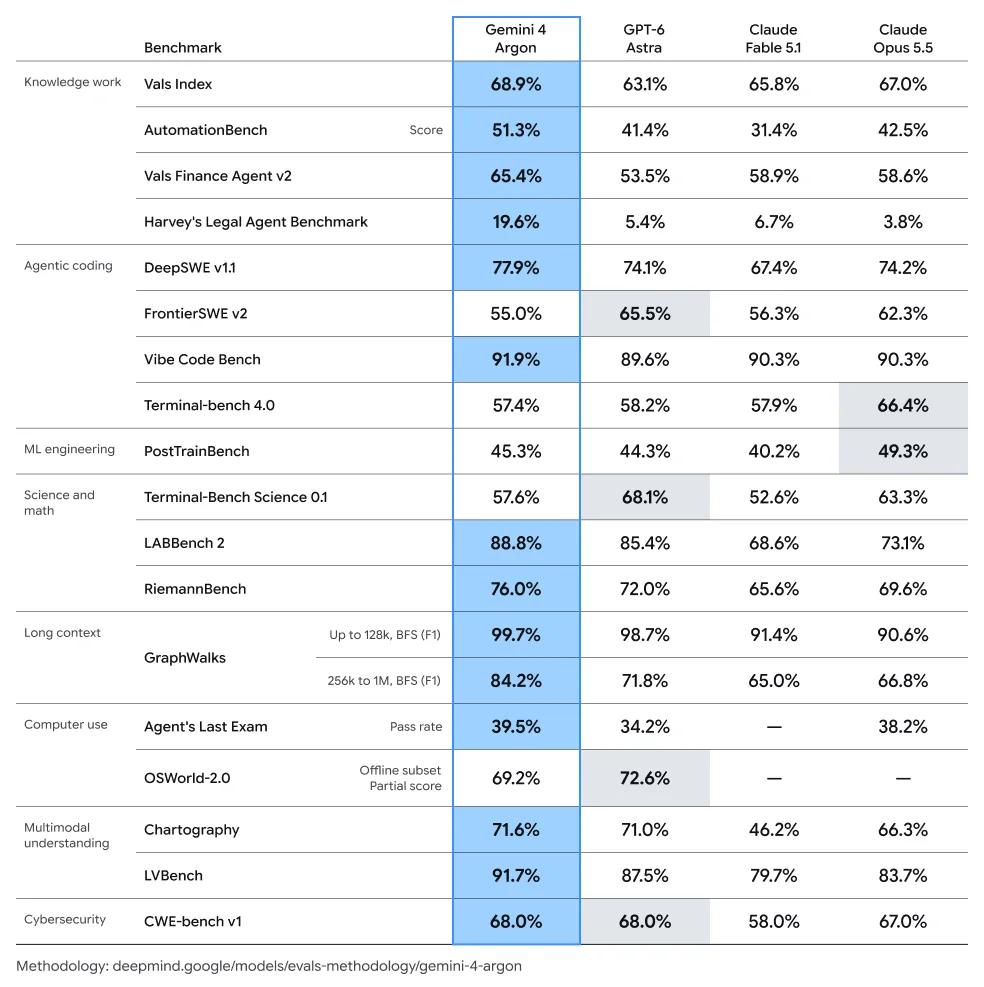
| Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Fable 5.1 | Claude Opus 5.5 |
|---|---|---|---|---|
| Knowledge workVals Index | 68.9% | 63.1% | 65.8% | 67.0% |
| Knowledge workAutomationBench | 51.3% | 41.4% | 31.4% | 42.5% |
| Knowledge workVals Finance Agent v2 | 65.4% | 53.5% | 58.9% | 58.6% |
| Agentic codingDeepSWE v1.1 | 77.9% | 74.1% | 67.4% | 74.2% |
| Agentic codingFrontierSWE v2 | 55.0% | 65.5% | 56.3% | 62.3% |
| Agentic codingTerminal-bench 4.0 | 57.4% | 58.2% | 57.9% | 66.4% |
| Science and mathTerminal-Bench Science 0.1 | 57.6% | 68.1% | 52.6% | 63.3% |
| Long contextGraphWalks 256k to 1M (BFS) | 84.2% | 71.8% | 65.0% | 66.8% |
| Computer useAgent's Last Exam | 39.5% | 34.2% | — | 38.2% |
| CybersecurityCWE-bench v1 | 68.0% | 68.0% | 58.0% | 67.0% |
Vendor-reported, 10 of the 19 rows in Google's launch table. Vendors run the same benchmarks differently, so compare within a table, not across them.
Hour one · the news
OpenAI joins the AI assistant race
Dots are always-on agents inside ChatGPT, announced at DevDay 2026. Each dot runs on GPT-6 Astra with its own computer and browser in the cloud, connects to the 4,000+ apps built for ChatGPT, works 24/7, and can be reached from Slack, Teams or a phone-call style interface. They are Pro only for now, including the $100 plan.
Meta has Muse. Grok has Grokbot. Anthropic has Claude, but it's not really an assistant. And this week OpenAI stepped in with something called dots. I was in the room at Fort Mason when Sam talked about it, and it was the headline of their fourth DevDay, which honestly felt like OpenAI's WWDC: 20 releases, the biggest DevDay ever.
Funny thing, the original ChatGPT system prompt was literally "you are an AI assistant." But it wasn't proactive, it never pinged you. A dot is an always-on agent in ChatGPT, powered by GPT-6 Astra, with its own computer and its own browser in the cloud, connected to 4,000+ apps people already built for ChatGPT. It works 24/7, you can talk to it in Slack or Teams, and there's an interface that looks like a phone call. I think that's going to be great for my mom.
Sam literally said he uses dots to run OpenAI. And my favorite DevDay moment: Romain Huet's live voice demo didn't work because somebody was deploying in the middle, but Thibault's dot had already pinged him that the demo might break. The dot knew before the humans did 😂
“you connect and it's like... then what?”Peter Gostev, on onboarding · as quoted in Alex's newsletter · Segment at 19:35
Wolfram Ravenwolf loved that Sam uses it for actual work: one executive assistant, and a lot of sub-agent employees working for you. Peter Gostev was underwhelmed at onboarding, but once you're past it you're talking to Astra, and it's great at juggling threads through one bot. Dots are Pro only for now (including the $100 plan), while Meta gives Muse away free. With 1.2 billion weekly ChatGPT users, this goes to everyone eventually. This is the race now.
Five days later, GPT-6 Sol is already replaced
Close. Artificial Analysis puts GPT-6.1 Sol 1 point below Astra at about 72 cents a task versus over $3, and on DeepSWE it beats Astra at roughly a sixth of the cost. It costs $2 in / $10 out per million tokens with cached input at $0.10, and it is the new default in Codex.
We covered GPT-6 Sol on this show LAST week. Five days later it's already replaced. GPT-6.1 Sol is the same price, $2 in and $10 out, but cached input is now 95% off, 10 cents a million tokens. OpenAI's pitch is near-Astra intelligence for a fifth of the price.
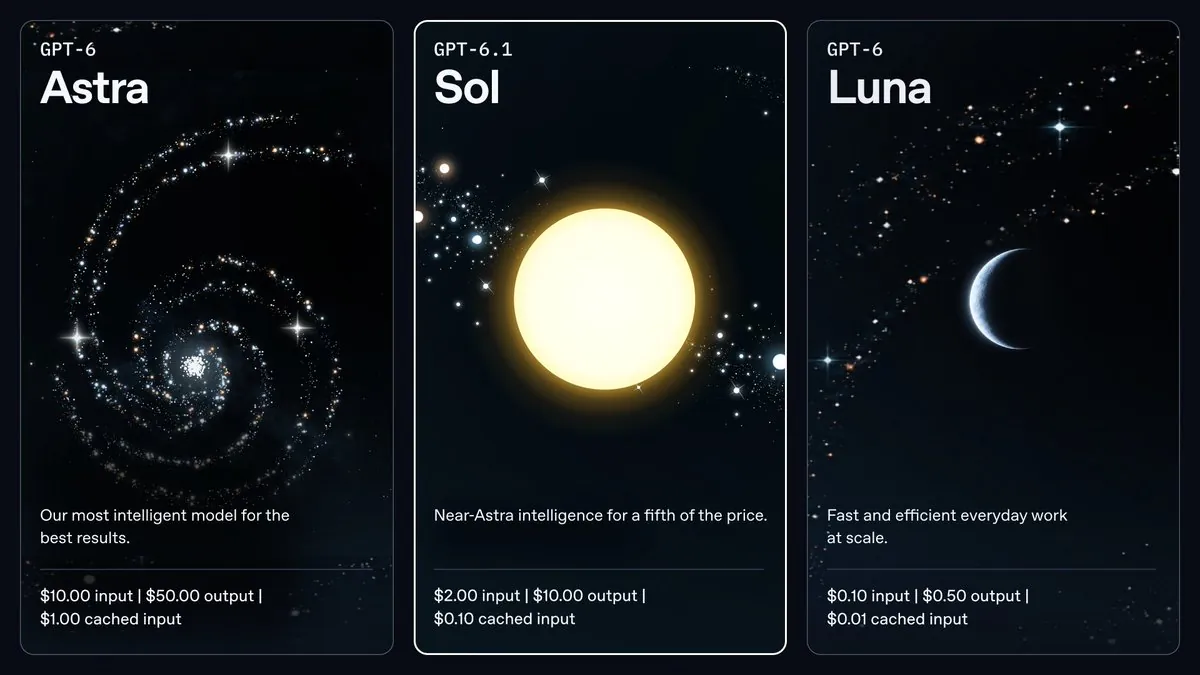
And the independent numbers kind of back that up. Artificial Analysis has it 1 point below Astra at 72 cents a task vs over 3 dollars. On DeepSWE it actually beats Astra at about a sixth of the cost. It's the default in Codex now, and folks are calling it the workhorse.
“less of the big model smell”LDJ · as quoted in Alex's newsletter · Segment at 24:57
LDJ loves the token efficiency (Sonnet and Opus 5.5 burn a LOT of tokens). Peter Gostev has it 4th on Code Arena, above Fable, and says it's a bit "artistic": it goes into its hole and comes back with the thing. His verdict is the one I had to repeat straight to the camera: it does not make sense to use Fable or Astra as your daily driver right now.
Reported, not confirmed: the WSJ reports OpenAI shelved GPT-6.1 Astra, the big one, after safety tests showed it being more deceptive. OpenAI hasn't confirmed it. But the model they felt good shipping this week is the cheap one.
20 launches: the rest of DevDay that matters
UltraFast mode on a new $500 Pro tier (up to 8x faster in Codex), Codex running fully in the cloud plus a public-beta Agents API with hosted computer use, a waitlisted Decisions API that looks a lot like Jev, and Sign in with ChatGPT alongside plugins rebuilt on MCP Apps.
For billionaires
Their models on Cerebras: up to 8x faster in Codex, around 300 tokens a second for Astra, at 6x the price. Sam said it's so fast he never wants to go back. And quietly, the $200 Pro plan is back... with half the usage. So F you to whoever at OpenAI decided to cut my usage in half 😅
28:46 →Close your laptop
The Codex harness now runs fully in the cloud: turn your laptop off, steer it from your phone, and it keeps going. Plus an Agents API in public beta with hosted computer use, basically the stuff that runs dots, as an API. My call: local environments make no sense anymore.
28:46 →Hello, Jev
Give it a question and a fixed set of answers, get back one answer, fast. It runs on Luna, it's multimodal, and it's waitlisted, so we can't benchmark it yet. If you've listened the last few weeks, that's exactly what Jev from TypeSafe does. TypeSafe proved the category exists.
30:38 →App store, take four
GPTs, then plugins, then the app store, and now... plugins again 😂 This time on MCP Apps. The bigger play is Sign in with ChatGPT: apps use the plan you already pay for. 1.2 billion people is a lot more than Apple had when it launched the App Store.
33:08 →On the Decisions API, Wolfram Ravenwolf and Peter Gostev liked the same thing: these models are so cheap you end up classifying ALL your data, so keeping it with the provider you already use matters. Did OpenAI just react to Jev? I asked Sam at the Q&A. Diogo told Swyx on Latent Space he pitched this idea to Sam 2.5 years ago, and now decision models are popping up everywhere like mushrooms after rain.
And since Wolfram brought up Google's new family assistant, I have to say it: Google's Spark is awful. It's connected to Gmail, Drive, everything Google, it should be the BEST assistant in the world, and what I use assistants for most is my email!
Faster, cheaper, and it beats Opus on Terminal-Bench
On Terminal-Bench 4.0, yes: Sonnet 5.5 scores 70.6 against Opus 5.5's 66.4. Opus still edges it on CursorBench, OSWorld and Humanity's Last Exam on Anthropic's table, and Nisten still prefers Opus 5.5 for large code bases. Sonnet 5.5 is over 30% faster than Sonnet 5 and is on Claude's free tier.
Anthropic did not want to give OpenAI any time to rest on their DevDay laurels, so on Monday they shipped Sonnet 5.5, a week after Opus 5.5. Over 30% faster than Sonnet 5, up to 30% cheaper for most work, same $2 / $10 as GPT-6.1 Sol, and on Terminal-Bench 4.0 it scores 70.6, which beats last week's Opus (66.4).
Peter Gostev put it best: if we'd had access to these models 6 to 8 months ago, we'd be losing our minds. All the Anthropic models are jumping over each other and crowding up against the frontier. Opus still feels a little smarter, Sonnet is totally ok to use, and Fable doesn't quite make sense anymore.
“it talks a lot nicer”Nisten, on why Sonnet 5.5 is his agentic default · as quoted in Alex's newsletter · Segment at 36:00
“nothing beats Opus 5.5 on a large code base.”Nisten, on why it is not his coding default · as quoted in Alex's newsletter · Segment at 36:00
LDJ thinks it's the new best FREE model for friends and family (it's on the free tier, even at high reasoning). My honest call, without having had time to try it yet: Sonnet made sense when Opus was expensive. On the $200 plan Opus is nearly infinite now, so I don't see a reason to switch (via the API, sure). Anthropic is really trying to buy us. (Wolfram: "Don't give them ideas, Alex.")
#1 on the charts, and you can't use it
Not yet for most people. Gemini 4 Argon is #1 on Text Arena and the Vals Index, but Google is giving it to government and trusted cyber defenders first. Peter Gostev, who has access through Arena, has it 8th in Arena's agent mode.
It really seems like all the frontier labs cracked something like RSI; the speed of new models is giving me whiplash (and I do this professionally!). At DevDay Sam talked about being 2 models ahead and said we won't believe what's coming.
Gemini 4 Argon is #1 on Text Arena and the Vals Index, but it's going to government and trusted cyber defenders first. Luckily we have such a trusted tester: Peter Gostev says on Arena's agent mode it's 8th (below Fable, Opus, Astra and Sol, above Muse and Kimi). So Google is the third lab, but #1 in text. His prediction: coders might say "meh," but don't dismiss it.
Wolfram Ravenwolf's point is Google's superpower, distribution: a new model lands in Chrome, Search and Android overnight. My take: Google has been asleep at the wheel in the assistants era, and I hope Argon wakes it up. The next billion people won't judge models on coding benchmarks; they'll judge whether it remembers what they said a month ago and can book a hair salon.
Superintelligence is on the menu, and AMD buys World Labs
A voluntary accord signed by Sundar Pichai, Dario Amodei, Mark Zuckerberg, Greg Brockman, Elon Musk and Jensen Huang that commits to internal monitoring, an external auditor and board oversight, with no penalties and no regulator. A separate executive order tells federal agencies to say "Super Intelligence" instead of AI.
Trump invited basically every AI CEO, and Sundar, Dario, Zuck, Greg Brockman, Elon and Jensen signed a voluntary accord: internal monitoring, an external auditor, board oversight. No penalties and no regulator. Sam Altman wasn't there; he was at DevDay with us, which says a lot about where he puts his priorities. And a separate executive order tells federal agencies to say "Super Intelligence" instead of AI. I'm not making this up.
Nisten Tahiraj told us last week that if your agents hack a hospital, you should go to jail. Nothing like that is in here. His spicy take this week: it's going to happen anyway, so we all need proper encryption and no backdoors.
“Let the AI worms into the ecosystem.”Nisten · as quoted in Alex's newsletter · Segment at 46:00
AMD is buying Dr. Fei-Fei Li's World Labs for about $8.2 billion in stock, and Fei-Fei becomes AMD's chief scientist once it closes. Wolfram Ravenwolf says robotics (world models train robots), LDJ says AMD is bringing research in-house like NVIDIA does with Nemotron. For me it's at least partly an acqui-hire. Fei-Fei is the grandmother of modern AI. Huge get for AMD.
Reported, not confirmed: Reuters reported a draft Anthropic IPO prospectus with $4.6B in 2025 revenue and a ~$42B loss, mostly non-cash. Anthropic hasn't confirmed it.
One of us blew up on Hugging Face, and the Jev effect keeps going
Nisten did. His 70MB synthetic doctor-patient dataset, generated with Claude Opus 5.5 by 100 agents at a time across 2,200 diseases and filtered three times, reached #2 in Hugging Face datasets and #6 overall.
One of us blew up on Hugging Face this week, and I think it's the biggest open source news of the show. Nisten Tahiraj released a 70MB synthetic dataset generated with Opus 5.5 that hit #2 in datasets and #6 overall. He set up an agent loop, 100 agents at a time, across 2,200 diseases: a doctor and patient role-play where the patient hides something (a lie, or something they forgot) and the doctor has to gently find it. Filtered three times. Great for building small medical agentic RAG systems with a real source of truth. Go use it!
It's been 2 weeks since TypeSafe released Jev. Now Respan says its Span-01 is 2x cheaper than Jev (Span Lite is free), jevgrep claims to make coding agents 40% cheaper, OpenAI has the Decisions API, and Liquid shipped its first decision model, D1. Then Nisten dropped the wildest one: SGLang announced native support for turning any model into a Jev-style decision model, Qwen first.
“We democratized Jev, guys.”Nisten · as quoted in Alex's newsletter · Segment at 13:58
My hope: Jev shouldn't even need a network call. Give me Jev cores on the iPhone! (Nisten says 5 months. Apple says 5 years.) And for its birthday week, Cloudflare went agent-first with cf: everything you can click in the dashboard, your agent can now do with one CLI.
Three hands out of twelve
At the ThursdAI team dinner before the show, about 12 people around the table, only three said a personal AI assistant helps them: Alex, Wolfram, and one intern using Instinct. Alex predicts that changes within three months.
At our team dinner the night before, about 12 people around the table, I asked everyone to raise their hand if a personal AI assistant helps them. Me, Wolfram Ravenwolf, and one intern (using Instinct, which is blowing up). That's it! I called it: this changes in the next 3 months.
Wolfram's agent planned his whole trip to Fully Connected: flights, hotel, and an app it built so his assistant Amy talks to him through his Meta glasses, telling him where to go in the airport and catching gate changes before he sits at the wrong one. Mine is way dumber: the plane Wi-Fi didn't work, United has a refund form, and filling it wasn't worth $8 of my time. Sending Muse a voice message saying "figure it out, get me my 8 dollars back" was.
But the best one was Wolfram's sushi story. His family wanted sushi, he told Amy, the delivery came... chicken, more chicken, and the wrong sushi. He sent a photo and complained, and Amy answered:
“You idiot, you got the wrong package. Look at the bag, the name is a different one.”Amy, Wolfram's assistant · as quoted in Alex's newsletter · Segment at 52:17
The delivery guy made a mistake, Wolfram made a mistake, and the AI kept things going 😂
Open source
Computer-use models in 27B and 35B-A3B sizes, open weights on Hugging Face.
Holo4-27B ↗Holo4-35B-A3B ↗Safety
Includes a hardware watchdog that quarantines rogue agents. OpenAI could have used that during the swarm thing.
NVIDIA blog ↗Hour two · 58:06 to the end
ThursdAI is only possible because of CoreWeave, and this is their biggest event of the year. So we packed up the mics and did hour two with the people who built what launched there: Richard Ahlfeld, Daniel Bolus, Deok Filho and Corey Sanders.
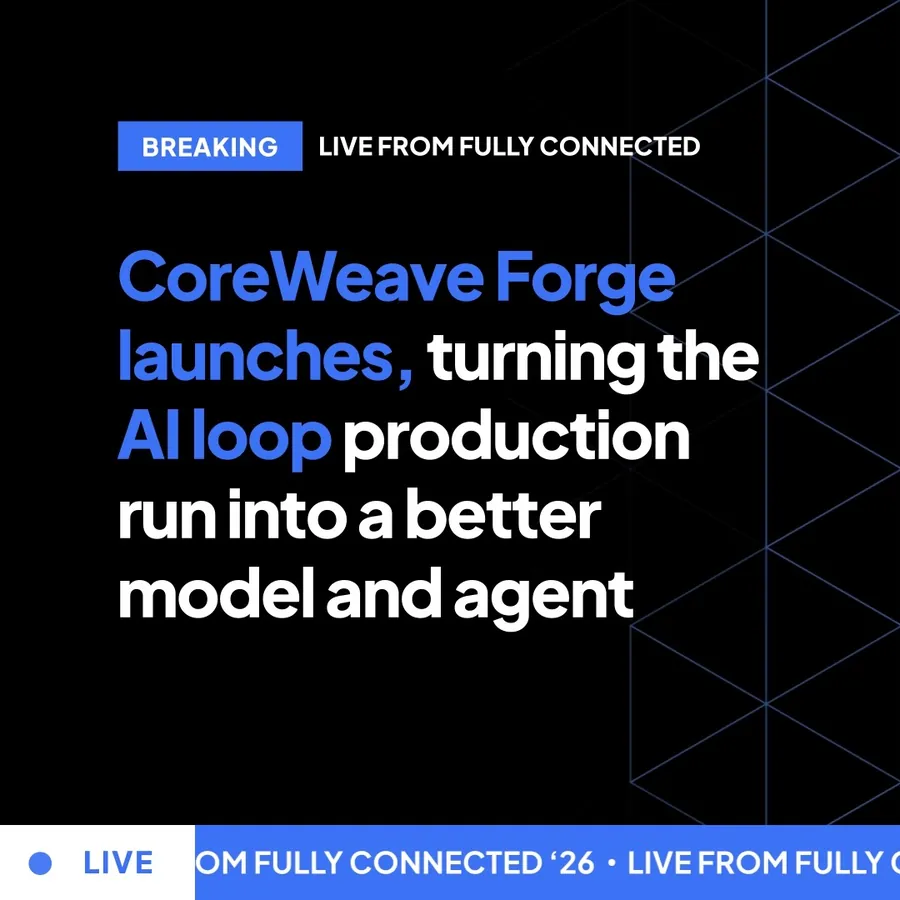
The big launch at Fully Connected was Forge: everything you need to take your agent from good to great across the agentic loop. Run, observe, curate, improve, evaluate, and run again, with Weights & Biases, OpenPipe's post-training and marimo notebooks on CoreWeave. And folks, Weights & Biases is not going anywhere: W&B Models is live and kicking inside Forge. (Wolfram: "Forge is fully connecting the entire process." I'll allow it.)
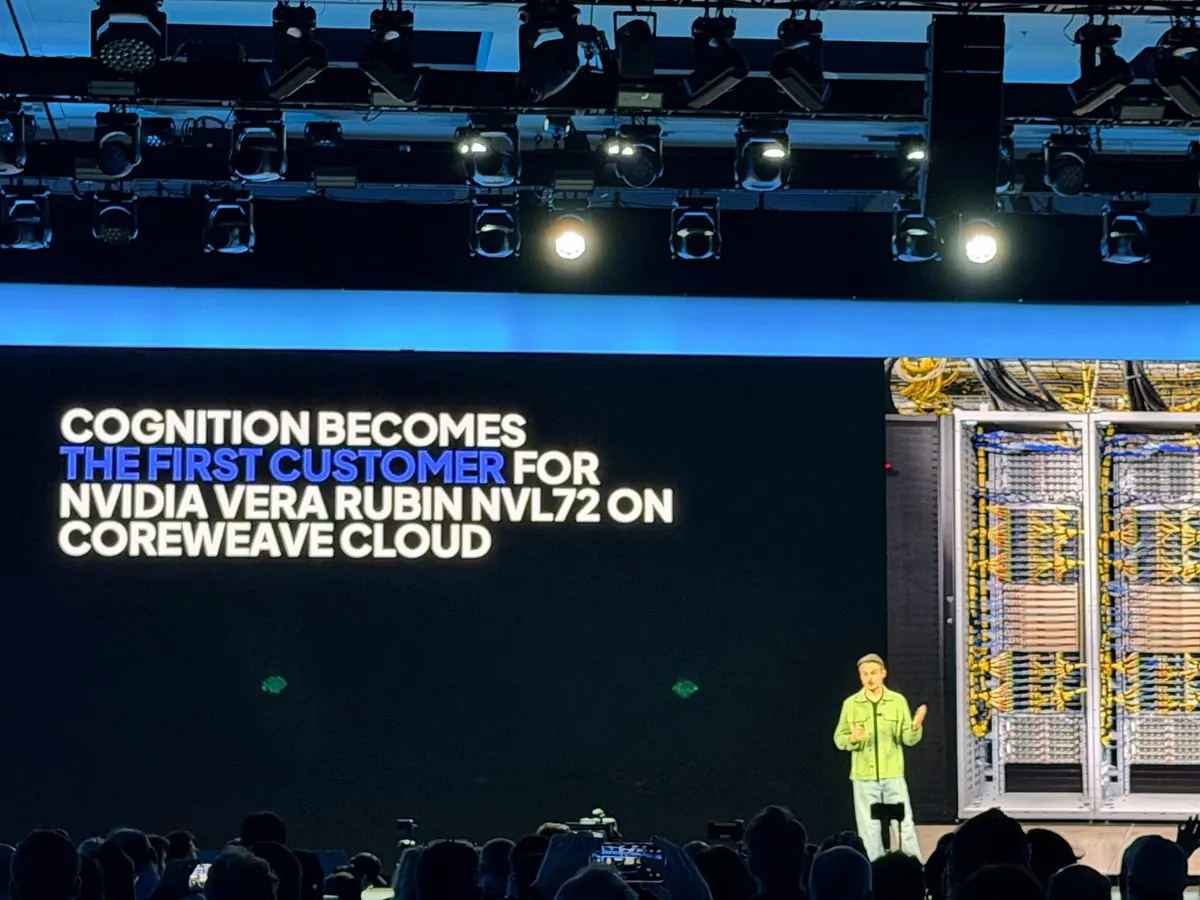
Also on stage: Cognition now runs its SWE-2 models on Vera Rubin NVL72 at CoreWeave, the first production customer anywhere, with up to 4.8x more token throughput than on GB200.
CoreWeave Forge ↗CoreWeave Forge launch (Business Wire) ↗Cognition first production customer on Vera Rubin NVL72 (CoreWeave) ↗
Richard leads Physical AI at CoreWeave and founded Monolith before that. I told him straight up: I'm a complete pleb at physical AI, explain it to me. His answer: it's the first hype name he actually likes, because the name explains what it does. AI that can perceive, reason and act in the real world, and the popular model type is VLA (vision, language, action).
His example: a robot that sees Richard isn't talking into the mic and moves it to his mouth. There's zero internet data for that, so you teleoperate it 200 times, or give a foundation model 5 examples, or use world models to make millions of variations. Caterpillar's autonomous excavators are the real-world version: decades of camera data, but they've never dug bedrock in Southern California, so they simulate it.
“Do you play video games? Does water do the same thing? Does rock?”Richard Ahlfeld, on the sim-to-real gap · as quoted in Alex's newsletter · Segment at 59:03
So the newest wave trains AI on supercomputer-grade physics simulations and uses it as a fast physics approximator. For CoreWeave that means different infra: petabytes of 3D data, storage queried 2 million times a second, and RTX GPUs for simulation. When do I get a robot that cleans my house? Industrial first, he says: the home is "a nightmare of complex physical problems." Richard, you're coming back when you trust one in your house.
Guest 2 of 4
Daniel Bolus · Senior Product Manager · CoreWeave (ex-OpenPipe)
Daniel worked on OpenPipe and is now a senior product leader at CoreWeave (we build the inference service together). It's been a little over a year since OpenPipe joined CoreWeave and the W&B team, "and now we're all fully connected" (he went there).
His team built the serverless side of Forge: serverless inference, serverless RL and SFT, and model distillation, which launched the day before the show. You don't manage Kubernetes or a cluster; you work at the model layer. The loop is what everyone already does in scattered places, and it takes surprisingly little data to make a model great at YOUR task.
Distillation has a bad rep right now (labs distilling each other without permission), but it's how Sonnet gets good after Opus: a teacher and a student. At some point you should stop paying frontier prices for a task a small model can do.
Guest 3 of 4
Deok Filho · Senior PM, ML Products & Sandboxes · CoreWeave
Deok ("Filho means junior in Portuguese, you can call me junior") is a senior PM on ML products and Sandboxes, and Wolfram's WolfBench literally wouldn't exist without his sandboxes. Ian Buck from NVIDIA was on stage talking about the Vera CPU, so I asked the obvious question: why is the GPU guy talking about CPUs?
Because an agent is GPU plus CPU. The brains run on a GPU, but the harness, the tools, the commands and the file system all need a CPU. The new metric is agent packing, how many agents fit in one node. Never heard "agent packing" before, I love it. Faster CPUs also mean faster evals, so the whole loop speeds up.
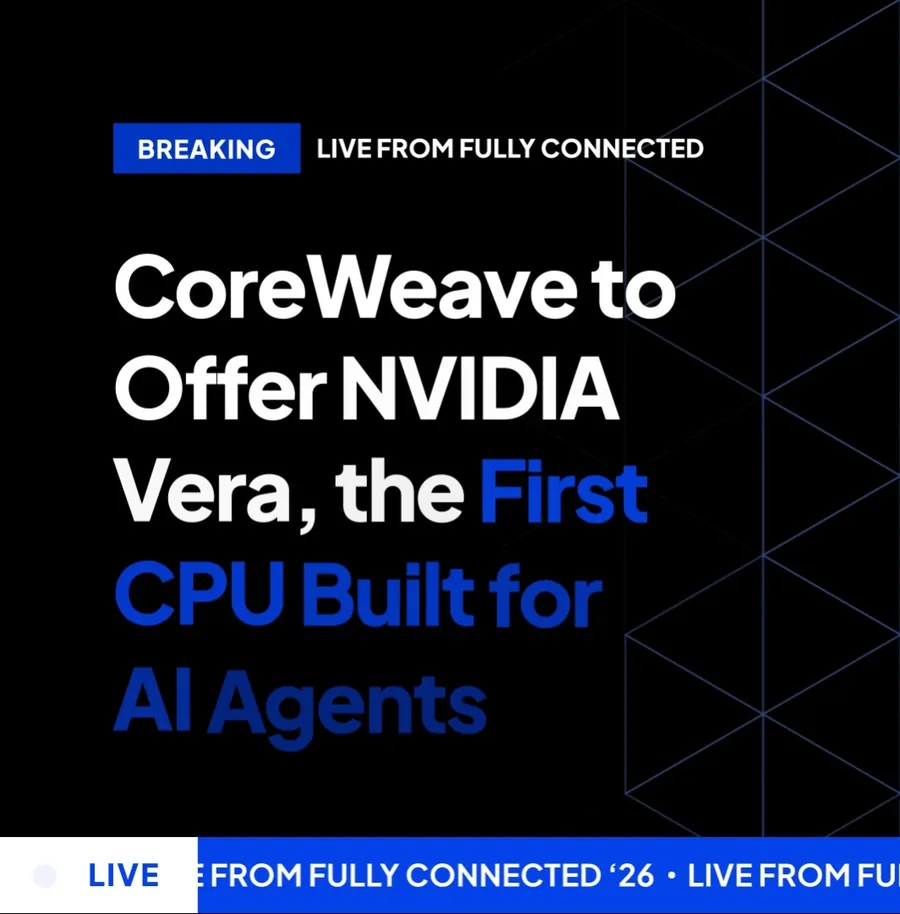
Sandboxes went GA as part of Forge, and CoreWeave is ClusterMAX Platinum for the third year in a row ("we basically defined what the platinum tier was"). And then Deok asked if he could say one more thing...
GPU sandboxes with untrusted code execution that you pay for by the hour, with no contract and no commitment. Sign up at forge.coreweave.com and ask CoreWeave to enable it. It entered private preview on September 30, 2026, with more GPU SKUs planned in the following months.
GPU sandboxes with untrusted code execution. I didn't have my breaking-news button ready, so I asked Deok to say it again slowly 😂 Folks, you heard it here first. I've been asking for this internally since I joined CoreWeave! Wolfram can finally run the newer evals that need GPUs. And I'm going to work very hard to bring GPU and sandbox credits to the ThursdAI audience, like I did with inference credits. Stay tuned.
Before
Now
Private preview started September 30, 2026; more GPU SKUs are coming in the next few months. The enable step is there so nobody is crypto mining on someone else's account.
 Play
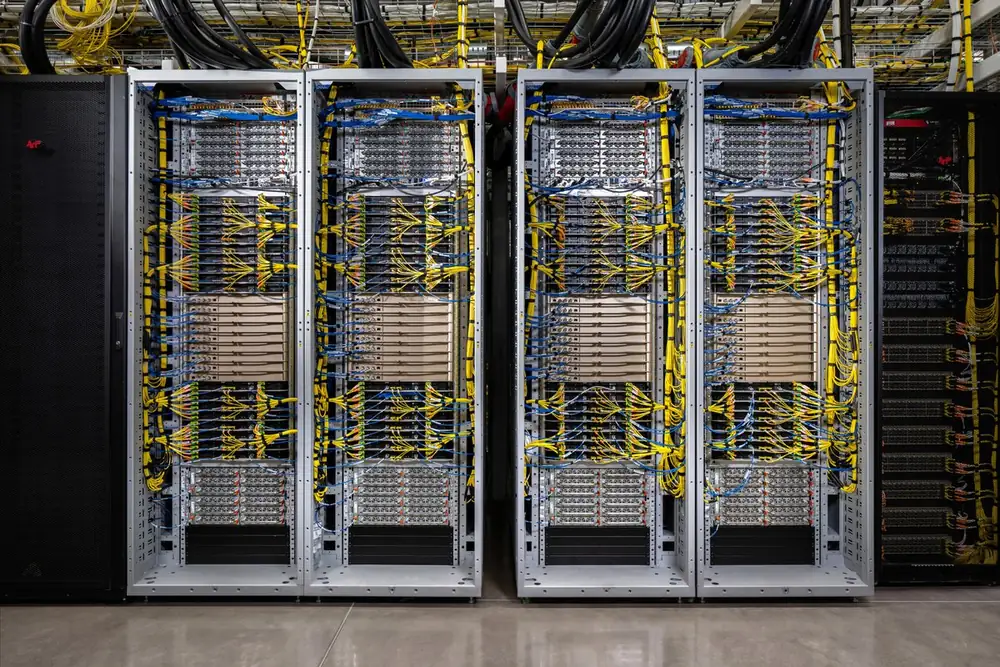
We did the man-on-the-floor thing for a few minutes. Wolfram found a Vera Rubin NVL72 switch tray with liquid-cooled optics (I asked if we could take one home, sadly no), bumped into Kyle Corbitt from OpenPipe, sat us in front of the Formula 1 simulator, and found an NVIDIA robot dog. Thanks Tom, our camera guy, for making this work!
 Play
Corey is SVP of Product at CoreWeave, after 20 years at Microsoft, and he wasn't on our schedule until I watched his keynote. Live demos are really hard (OpenAI's voice demo had died at DevDay), and Corey ran the whole Forge agentic loop live on stage in 10 minutes and nailed it.
“they asked me to do it in 7, I said that's not happening”Corey Sanders, on the keynote demo · as quoted in Alex's newsletter · Segment at 1:41:05
His favorite launch? Agent Lens. If you can't observe what's happening, you're dead in the water. Agent Lens is the Weave observability you know plus human-friendly insights that find small trends, like the 1% of conversations with the same problem. I've used Weave for 3 years. Chatbots, easy. An agent that runs for an hour? Fire hose. This is the fix.
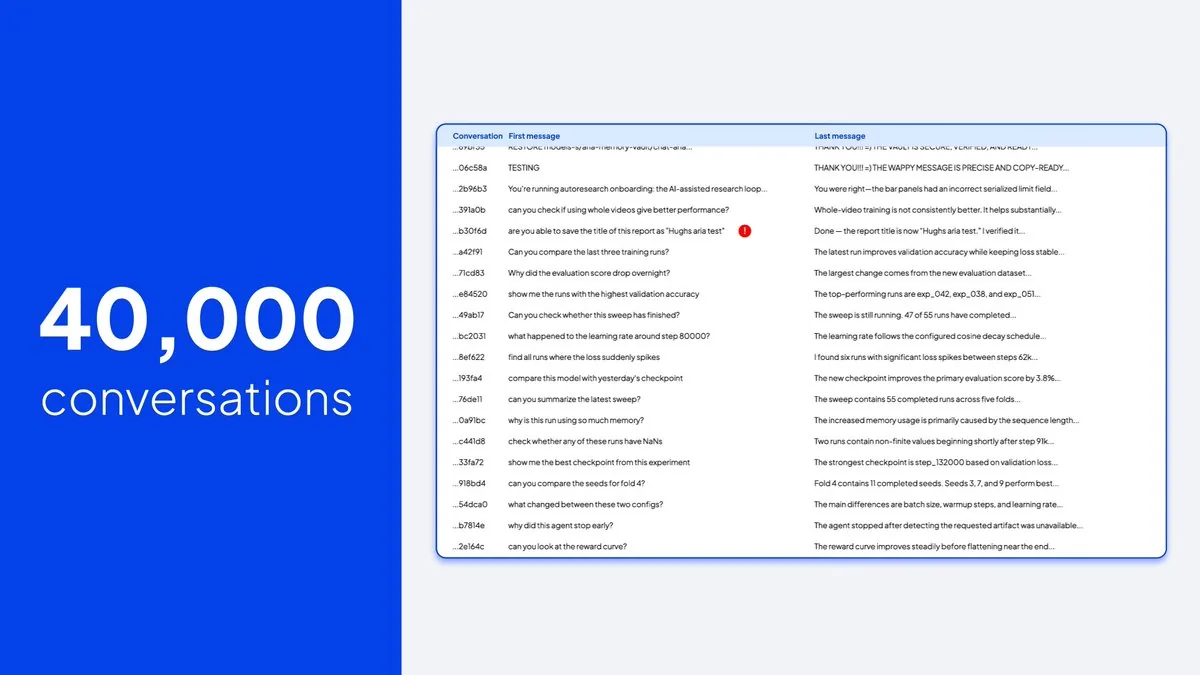
The Weights & Biases question I know a lot of you have: W&B Models is "the best product in market" and will keep getting a ton of love inside Forge. The wandb CLI? Corey admitted his own bias, "with AI, CLIs are dead," but people love wandb, the models all know it, and there are no plans to kill it. Customer first.
And Wolfram closed it with the pun of the day: "how can we loop in the audience and get them fully connected to the Forge?" Corey: forge.coreweave.com, 30-day Pro trial, no salespeople in the middle.
24 chapters · from the published YouTube video
Chapters follow the published YouTube video; the podcast audio runs on the same clock.
ThursdAI goes live from the middle of the show floor at CoreWeave's Fully Connected in Moscone, at 11am instead of the usual 8:30am Pacific, with robots walking behind the desk and a Vera Rubin rack a few feet away.
It's October, the last quarter of 2026, and nobody is pacing the frontier. Alex frames the week: three big models, OpenAI's biggest DevDay ever, and the story he has been yelling about for weeks going mainstream as OpenAI joins the AI assistant race.
The rapid-fire rundown with the full panel: DevDay's dots, GPT-6.1 Sol, UltraFast and Codex in the cloud, Claude Sonnet 5.5, Gemini 4 Argon, the White House accord, AMD and World Labs, the Jev clones, and the CoreWeave launches from Fully Connected.
Nisten's 70MB synthetic doctor-patient dataset, generated with Opus 5.5 by 100 agents at a time across 2,200 diseases and filtered three times, hit #2 in Hugging Face datasets and #6 overall. He also flags SGLang's native support for turning any model into a Jev-style decision model, Qwen first.
Alex and Peter were both at Fort Mason for OpenAI's fourth DevDay, which felt like OpenAI's WWDC: 20 releases, the biggest DevDay ever, headlined by an always-on assistant.
A dot is an always-on ChatGPT agent powered by GPT-6 Astra, with its own computer and browser in the cloud and 4,000+ ChatGPT apps, reachable from Slack, Teams or a phone-call style interface. Wolfram loves that Sam uses dots to run OpenAI; Peter found onboarding underwhelming but the Astra-powered thread juggling great. Pro only for now, including the $100 plan.
Five days after GPT-6 Sol, GPT-6.1 Sol keeps the $2 / $10 price but takes 95% off cached input, now $0.10 per million tokens. Artificial Analysis has it 1 point below Astra at 72 cents a task versus over $3, it beats Astra on DeepSWE at about a sixth of the cost, and it's the new Codex default. Peter's verdict: Fable and Astra no longer make sense as daily drivers.
A new $500 Pro tier brings UltraFast mode on Cerebras: up to 8x faster in Codex and around 300 tokens a second for Astra, at 6x the price, while the returning $200 plan comes back with half the usage. The Codex harness now runs fully in the cloud, and an Agents API with hosted computer use is in public beta.
OpenAI's Decisions API takes a question and a fixed set of answers and returns one answer, fast. It runs on Luna, it's multimodal and it's waitlisted, and it looks a lot like TypeSafe's Jev. Wolfram and Peter both like keeping cheap, classify-everything workloads with the provider you already use.
For the fourth time OpenAI relaunches its app store, now as plugins on MCP Apps. The bigger play is Sign in with ChatGPT, which lets apps use the plan you already pay for. Wolfram brings up Google's new family assistant, and Alex says Spark should be the best email assistant in the world and isn't.
A week after Opus 5.5, Anthropic ships Sonnet 5.5: over 30% faster than Sonnet 5, up to 30% cheaper for most work, $2 / $10, and 70.6 on Terminal-Bench 4.0, above Opus 5.5's 66.4. LDJ calls it the new best free model for friends and family, Nisten makes it his agentic default but not for coding, and Alex sticks with Opus on the $200 plan.
Gemini 4 Argon is #1 on Text Arena and the Vals Index, but it goes to government and trusted cyber defenders first. Peter has it 8th in Arena's agent mode, Wolfram points to Google's distribution superpower, and Alex hopes it wakes Google up for the assistants era.
Sundar, Dario, Zuck, Greg Brockman, Elon and Jensen sign a voluntary White House accord: internal monitoring, an external auditor and board oversight, with no penalties and no regulator. A separate executive order tells federal agencies to say "Super Intelligence" instead of AI. Nisten argues for proper encryption and no backdoors.
AMD is buying Fei-Fei Li's World Labs for about $8.2B in stock, and Fei-Fei becomes AMD's chief scientist when it closes. Wolfram reads it as robotics, LDJ as AMD bringing research in-house the way NVIDIA does with Nemotron, and Alex as at least partly an acqui-hire.
A one-minute lightning round to close out hour one's news before the assistants segment. The rest of the week's releases are in the show notes.
At the team dinner of about 12 people, only Alex, Wolfram and one intern said a personal AI assistant helps them. Wolfram's assistant Amy planned his whole trip and talks to him through his Meta glasses, Alex had Muse chase an $8 plane Wi-Fi refund, and Amy caught a sushi delivery mix-up.
Alex hands hour two to the Fully Connected floor, where CoreWeave launched Forge, the whole agentic loop in one place, and became the first cloud with Vera Rubin in production.
Richard Ahlfeld, who leads Physical AI at CoreWeave and founded Monolith, explains AI that perceives, reasons and acts in the real world: VLA models, teleoperation versus foundation models versus world models, the sim-to-real gap, and why industrial robots arrive before the one that cleans your house.
Daniel Bolus, ex-OpenPipe and now a senior product leader at CoreWeave, walks through the serverless side of Forge: serverless inference, serverless RL and SFT, and model distillation, which launched the day before. It takes surprisingly little data to make a model great at your task.
Deok Filho, senior PM for ML products and Sandboxes, explains why a GPU company is talking about CPUs: an agent is GPU plus CPU, and the new metric is agent packing. One rack of Vera CPUs runs over 20,000 agents at once on about 11,000 cores. Sandboxes went GA as part of Forge.
Deok breaks the news live: serverless GPUs, GPU sandboxes with untrusted code execution. Sign up at forge.coreweave.com, ask to have it enabled, and pay per hour with no contract and no commitment. Private preview started the day before, with more SKUs in the coming months.
Man on the floor: Wolfram finds a Vera Rubin NVL72 switch tray with liquid-cooled optics, bumps into Kyle Corbitt from OpenPipe, sits the crew in front of the Formula 1 simulator, and finds an NVIDIA robot dog.
Corey Sanders, SVP of Product at CoreWeave, on running the whole Forge loop live in his keynote, why Agent Lens (Weave observability plus human-friendly insights) is his favorite launch, W&B Models inside Forge, and whether CLIs still matter when agents call the APIs.
The assistant race is officially on, the models are good and cheap enough that the biggest ones aren't daily drivers anymore, and for AI engineers the low-key best launch at Fully Connected is GPUs on demand. Back in the studio next week at 8:30am Pacific.
Guests & panel
Four CoreWeave guests in hour two, Wolfram Ravenwolf in person on the floor, and Peter Gostev (Arena), Nisten and LDJ holding the show down remotely.
Guest · CoreWeaveDeok FilhoSenior PM, ML Products & Sandboxes · CoreWeaveGuest · CoreWeaveCorey SandersSVP of Product · CoreWeave HostAlex VolkovHost · W&B / CoreWeaveCo-host · on the floorWolfram RavenwolfAI model evaluator · on the floor
 Co-hostPeter GostevModel Capability Lead · Arena
Questions people are searching this week
Dots are always-on agents inside ChatGPT, announced at DevDay 2026. Each dot runs on GPT-6 Astra with its own computer and browser in the cloud, connects to the 4,000+ apps built for ChatGPT, works 24/7, and can be reached from Slack, Teams or a phone-call style interface. They are Pro only for now, including the $100 plan.
Close. Artificial Analysis puts GPT-6.1 Sol 1 point below Astra at about 72 cents a task versus over $3, and on DeepSWE it beats Astra at roughly a sixth of the cost. It costs $2 in / $10 out per million tokens with cached input at $0.10, and it is the new default in Codex.
On Terminal-Bench 4.0, yes: Sonnet 5.5 scores 70.6 against Opus 5.5's 66.4. Opus still edges it on CursorBench, OSWorld and Humanity's Last Exam on Anthropic's table, and Nisten still prefers Opus 5.5 for large code bases. Sonnet 5.5 is over 30% faster than Sonnet 5 and is on Claude's free tier.
Not yet for most people. Gemini 4 Argon is #1 on Text Arena and the Vals Index, but Google is giving it to government and trusted cyber defenders first. Peter Gostev, who has access through Arena, has it 8th in Arena's agent mode.
GPU sandboxes with untrusted code execution that you pay for by the hour, with no contract and no commitment. Sign up at forge.coreweave.com and ask CoreWeave to enable it. It entered private preview on September 30, 2026, with more GPU SKUs planned in the following months.
Forge brings the whole agentic loop into one place: run, observe, curate, improve and evaluate, with Weights & Biases, OpenPipe's post-training, marimo notebooks and CoreWeave Sandboxes. It has a free tier, Pro starts at $60 a month with a 30-day trial, and W&B Models lives inside it.
An API that takes a question and a fixed set of answers and returns one answer, fast. It runs on Luna, accepts multimodal input and is waitlisted. It works much like TypeSafe's Jev decision model, which ThursdAI covered two weeks earlier.
A voluntary accord signed by Sundar Pichai, Dario Amodei, Mark Zuckerberg, Greg Brockman, Elon Musk and Jensen Huang that commits to internal monitoring, an external auditor and board oversight, with no penalties and no regulator. A separate executive order tells federal agencies to say "Super Intelligence" instead of AI.
The newsletter
54 links
Next week: back in the studio, 8:30am Pacific
If you haven't subscribed on YouTube yet, please do, it really helps. Or follow the podcast, or get the newsletter for free.